/
/
·
·
·
·
·
·
Good software architecture isn't about predicting the future. It's about making today's decisions without unnecessarily limiting tomorrow's options. Reflections on modularity, maintainability, and building systems that can evolve as products grow.
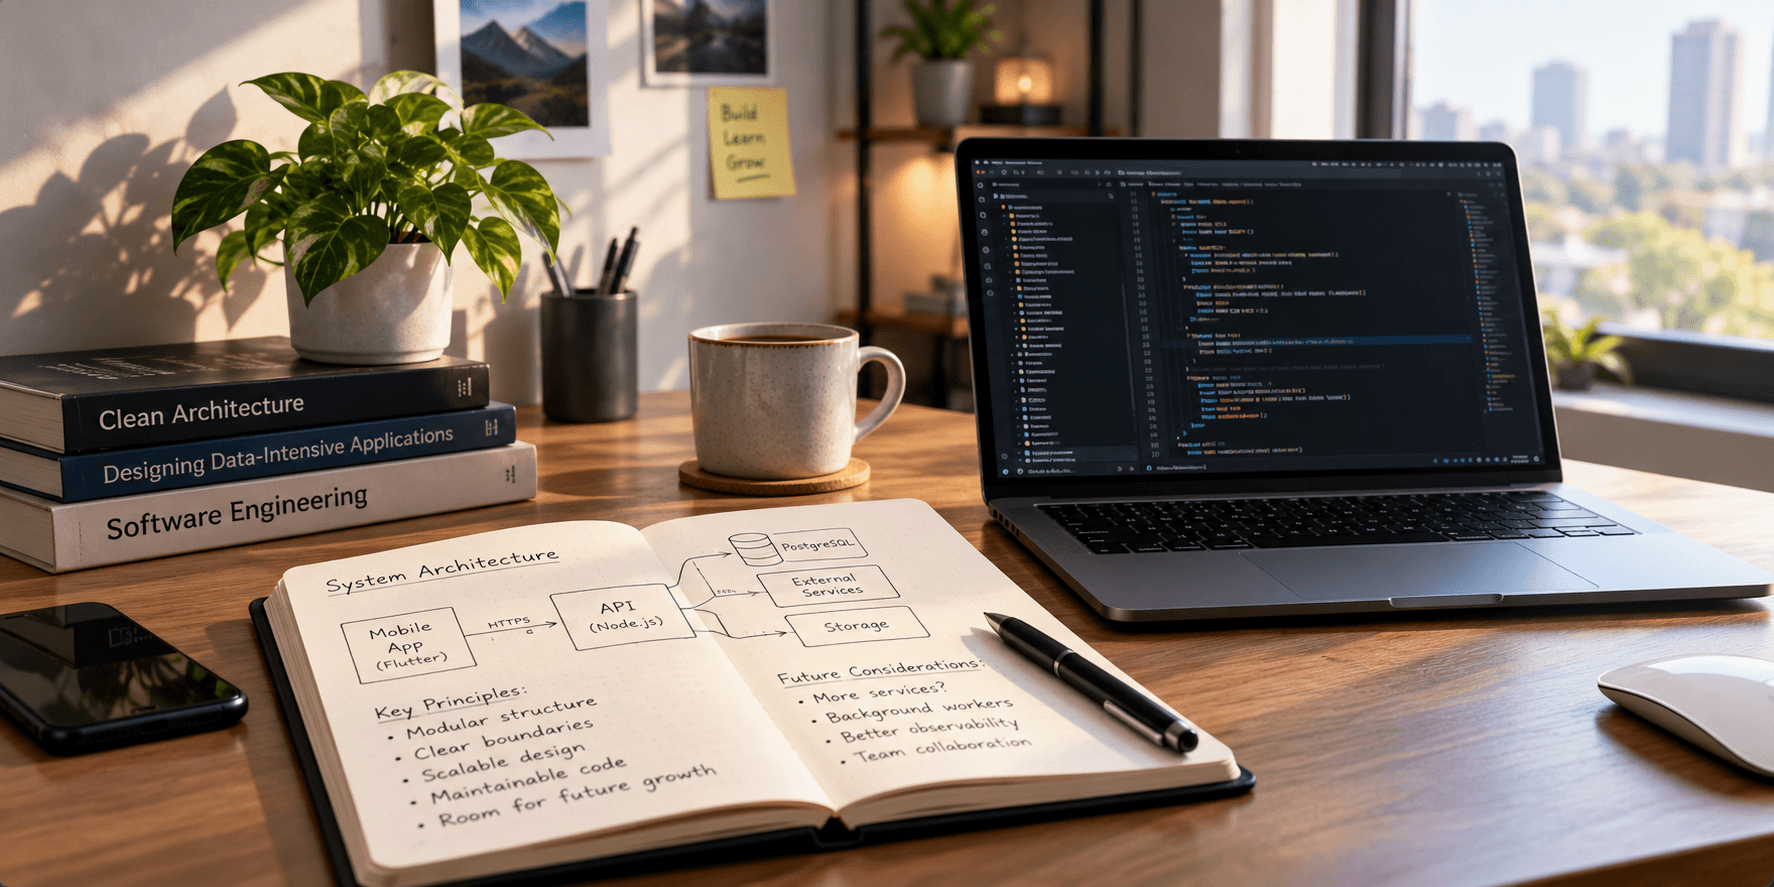
Good software architecture isn't about predicting the future. It's about making today's decisions without unnecessarily limiting tomorrow's options.
When I started working on software projects, it was easy to think of architecture as something that needed to be designed correctly from the beginning. Choose the right folder structure, pick the right technologies, separate the responsibilities, and build a foundation that could support everything the product might eventually become.
Over time, I've come to see architecture a little differently.
Software rarely develops exactly as we imagine it at the beginning. Requirements change, features become more complicated, new integrations appear, and a product starts serving needs that weren't obvious when development first began.
I've worked across mobile applications and backend services, and I've become increasingly interested in a practical question: How do we build software that can evolve without making every new requirement unnecessarily expensive?
I don't think the answer is to design for every possible future. I think it's to make deliberate decisions today while leaving reasonable room for change.
A project usually begins with a relatively clear understanding of what needs to be built. The initial requirements define the main features, the expected users, and the technologies that seem appropriate.
But the first version of a product rarely tells the whole story.
A simple feature can grow into a complicated workflow. A backend that initially serves one application may eventually support several clients. A component that seemed reusable may turn out to have responsibilities that are too different to share comfortably.
These changes are not necessarily signs of poor planning. They are part of building software in a changing environment.
The problem begins when the original implementation makes every change harder than it needs to be.
For example, if business rules are tightly coupled to a particular API handler, changing those rules may require modifying code that also handles request validation, database operations, and response formatting. A small requirement can turn into a change across several unrelated parts of the system.
We cannot eliminate change. But we can avoid creating unnecessary dependencies that make change expensive.
One mistake I've learned to be cautious about is introducing complexity for requirements that don't exist yet.
It is tempting to anticipate every future possibility: separate services for every domain, abstractions around every dependency, elaborate interfaces for components that have only one implementation, or infrastructure designed for a scale the product has not reached.
Some of these decisions become valuable when the need is real. Before that point, they can add more maintenance work than flexibility.
A smaller system can still have good architecture.
For me, the important questions are:
These questions are more useful than asking whether a project follows the most sophisticated architectural pattern.
The goal is not to make a codebase look architecturally impressive. It is to make the codebase understandable and adaptable for the people who will maintain it.
As I've worked across mobile applications and backend development, I've found myself paying more attention to boundaries between responsibilities.
A boundary gives a part of the system a reasonably clear purpose and limits how much it needs to know about other parts.
On the backend, for example, organizing code around features can make responsibilities easier to locate. A project with separate areas for authentication, users, or orders can be easier to navigate than one where every controller, service, and data-access file is grouped into a large global folder.
That structure alone doesn't guarantee good architecture. A feature-based codebase can still contain tightly coupled services, duplicated business rules, or unclear ownership of data.
The more important principle is that related behavior should be easy to find, and dependencies should be intentional.
The same idea applies to mobile applications. User interface code, application logic, state management, and communication with backend APIs have different responsibilities. Keeping those responsibilities reasonably separated can make a feature easier to understand and modify.
I don't believe every project needs the same number of layers. The appropriate boundaries depend on the product, the team, and the complexity of the problem.
What matters is that the structure helps developers reason about changes rather than forcing them to understand the entire application before making a small modification.
Modularity is often discussed in terms of folders, packages, modules, or services. Those structures matter, but they are not the whole story.
I find it more useful to think about modularity in terms of change.
Suppose a product adds a new workflow. In a reasonably modular system, I should be able to identify the relevant business rules, understand their dependencies, make the change, and verify the affected behavior without navigating unrelated parts of the codebase.
In a tightly coupled system, the same change may require updates across many files because responsibilities are mixed together or because multiple components depend on implementation details they don't actually need.
The distinction isn't simply the number of files changed. Some features legitimately cross several boundaries. The question is whether those changes are expected and understandable, or whether they reveal dependencies that have become difficult to manage.
This is why I value separation of concerns, explicit interfaces where they provide value, and limited dependency between unrelated features.
I also try to avoid abstraction for its own sake. An abstraction is useful when it clarifies a responsibility, protects a meaningful boundary, or reduces a real source of change. It is less useful when it adds another layer that developers must understand without providing a corresponding benefit.
As backend systems grow, microservices can seem like the natural next step. They offer independent deployment, clearer service-level boundaries when designed well, and opportunities to scale individual components separately.
But they also introduce operational responsibilities: network communication, service-to-service authentication, distributed failure handling, observability, deployment coordination, and data consistency across services.
Those costs are real, even when the application is still relatively small.
For many products, a modular monolith is a practical starting point. The application runs as one deployable system, while its internal code is organized around clear business capabilities and controlled dependencies.
This doesn't mean a modular monolith is always better than microservices. It means the architecture should reflect the constraints and requirements that actually exist.
If a particular domain eventually needs independent scaling, deployment, or ownership, a well-separated module can provide a more understandable starting point for extracting that capability.
That extraction is not automatically easy. It may require redesigning data ownership, replacing in-process calls with network communication, and handling distributed failure modes. Good internal boundaries reduce some of the difficulty, but they do not eliminate it.
I see modularity as a way to preserve options, not as a promise that a future migration will be effortless.
Thinking about future growth is useful, but it becomes counterproductive when every possible scenario influences the initial design.
I prefer to distinguish between two kinds of decisions.
Decisions that are expensive to reverse deserve more careful thought. Examples may include a poorly chosen data model, unclear ownership of business rules, or a dependency structure that makes core functionality difficult to isolate.
Decisions that are inexpensive to change can often be made more simply. A local implementation detail, a small utility, or a UI component may not need a generalized abstraction until a real requirement justifies one.
This distinction helps balance preparation with progress.
It also encourages a useful habit: when introducing complexity, identify the problem that complexity is solving.
If a new layer protects an important boundary, it may be worth the cost. If a new service exists only because the system might someday become large, I would want a stronger reason before introducing it.
Good architecture is not the absence of trade-offs. It is being aware of the trade-offs and choosing them deliberately.
Architecture is not only about how code executes. It also affects how people work with the codebase.
In a team, a developer should be able to locate a feature's responsibilities, understand its dependencies, and make a change without relying on undocumented knowledge held by one person.
Clear naming, predictable project structure, consistent conventions, and understandable boundaries reduce the amount of context someone needs before contributing.
This becomes particularly important as a project grows or team responsibilities change.
A clever implementation may be perfectly understandable to the person who wrote it. A maintainable implementation should also be understandable to another developer who encounters it months later.
That doesn't mean every line needs extensive documentation or every decision requires a formal design document. It means the code should communicate its intent, and important architectural decisions should have explanations when their reasoning is not obvious.
I see maintainability as part of engineering quality because software is rarely written once and left untouched. It is read, modified, debugged, extended, and handed over repeatedly.
I don't have a universal checklist that produces the right architecture for every project. However, there are a few questions I find useful when making design decisions.
None of these principles prevents mistakes. They simply provide a more deliberate way to make decisions and recognize when an existing design is becoming a constraint.
I've come to believe that good architecture is less about getting everything right at the beginning and more about making future changes manageable.
We cannot predict every requirement, every integration, or every constraint a product will encounter. Trying to do so can lead to systems that are complicated before they have earned that complexity.
At the same time, moving quickly without considering boundaries can create a codebase where even small changes become risky.
The balance lies somewhere between those extremes: solve the problem in front of you, keep responsibilities clear, understand the cost of your abstractions, and avoid coupling today's implementation too tightly to assumptions about tomorrow.
A good architecture does not guarantee that a system will never need significant changes. Sometimes the requirements change enough that a substantial redesign is the right decision.
What it should do is make ordinary evolution less painful and make necessary architectural changes easier to reason about.
I want to build software that can grow with the product—not software that needs to be fought every time the product grows.
These are principles I'm continuing to develop through my work across mobile applications and backend systems. I expect my approach to architecture to evolve as I encounter new problems, constraints, and trade-offs.